Nvidia Cosmos 3 Super Text-to-Image
nvidia/cosmos-3-super/text-to-imageCosmos3 is a collection of Omnimodal world models capable of generating dynamic, high-quality video, image, audio, and action commands from combinations of text, image, video, and action trajectory inputs.
Set up the model and run your first generation.
Ctrl ⏎Examples
Runs published with this model. Load one into the playground and change whatever you like.
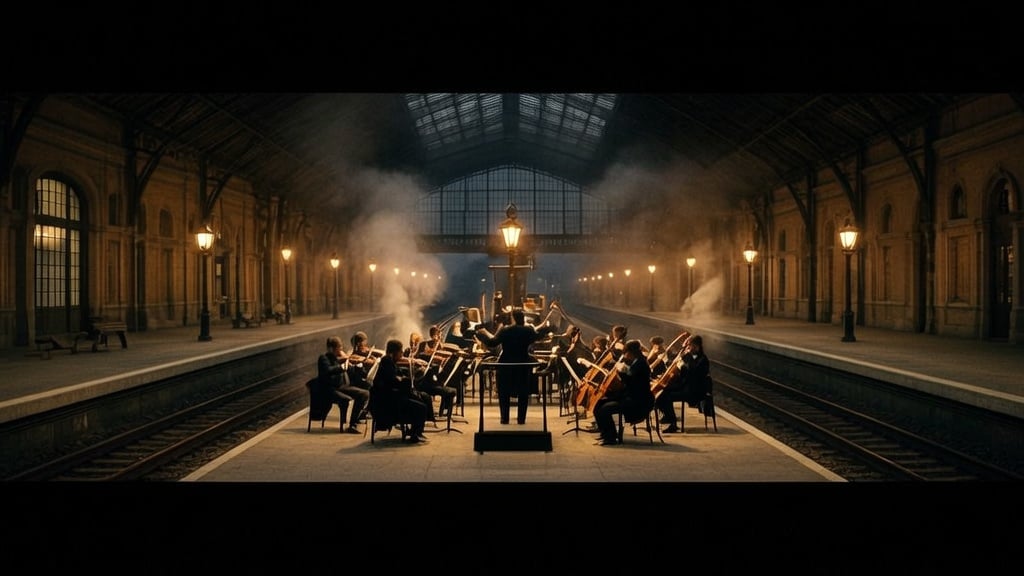
A symphony orchestra performing inside a grand European train station after the last train has departed. Empty platforms stretch into darkness while warm lantern light illuminates the musicians. Steam drifts through the air, creating a dreamlike cinematic atmosphere. Emotional storytelling, movie still, ultra realistic.
Providers
Where this model can run, priced for your account. Auto routing picks the top row and moves down it if a provider fails.
| Provider | Price | Speed | Completed |
|---|---|---|---|
| fal.aiLowest price | $0.040 /gen | — | — |
| Atlas Cloud | $0.044 /gen | — | — |
| OpenRouter | — | — | — |
| Replicate | — | — | — |
Speed and reliability appear once this platform has enough recent runs on a provider.
Questions
- $0.044 per generation on ElliSekiz — the provider's own price, billed 1:1 from a prepaid USD balance with no markup and no subscription. Failed generations are free.
- fal.ai, Atlas Cloud, OpenRouter, Replicate. Requests route to the cheapest available provider automatically, or you can pin one per request or per model.
- POST to https://ellisekiz.ai/api/v1/generations with "model": "nvidia-cosmos-3-super-text-to-image" and your prompt, authenticated with an ElliSekiz API token. The API tab on this page has the full request for this model, including its own parameters.
- negative_prompt, num_inference_steps, guidance_scale, output_format, seed, enable_safety_checker — each one is in the playground form on this page and in the API example.